AI Inference Memory: How HBF, CXL and CMX Cut Costs
Inference makes AI memory capacity and cost efficiency as important as speed. HBF, CXL memory pooling and NVIDIA’s CMX each add a tier below HBM to hold KV cache and context more cheaply.

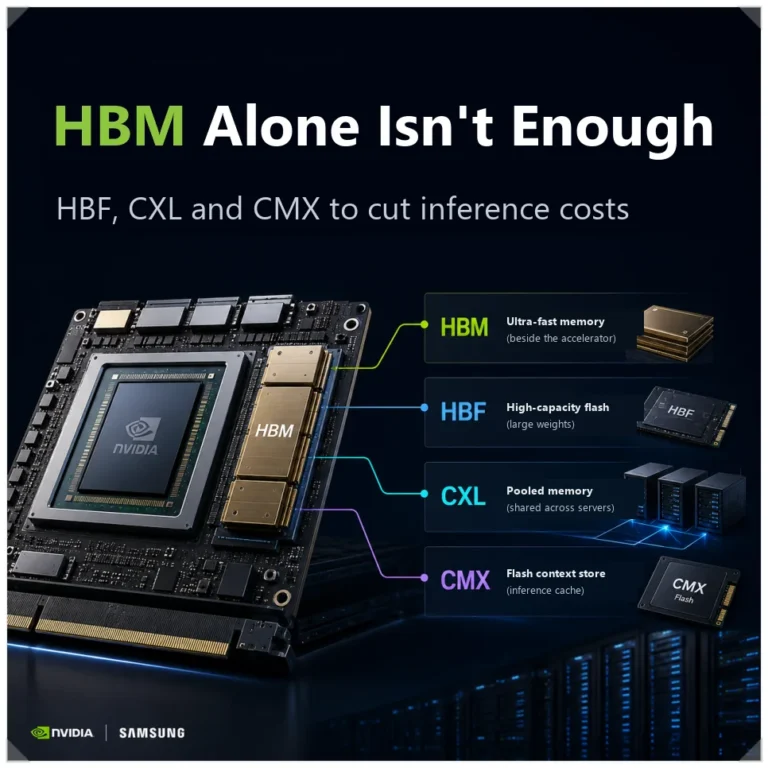
Inference makes AI memory capacity and cost efficiency as important as speed. HBF, CXL memory pooling and NVIDIA’s CMX each add a tier below HBM to hold KV cache and context more cheaply.
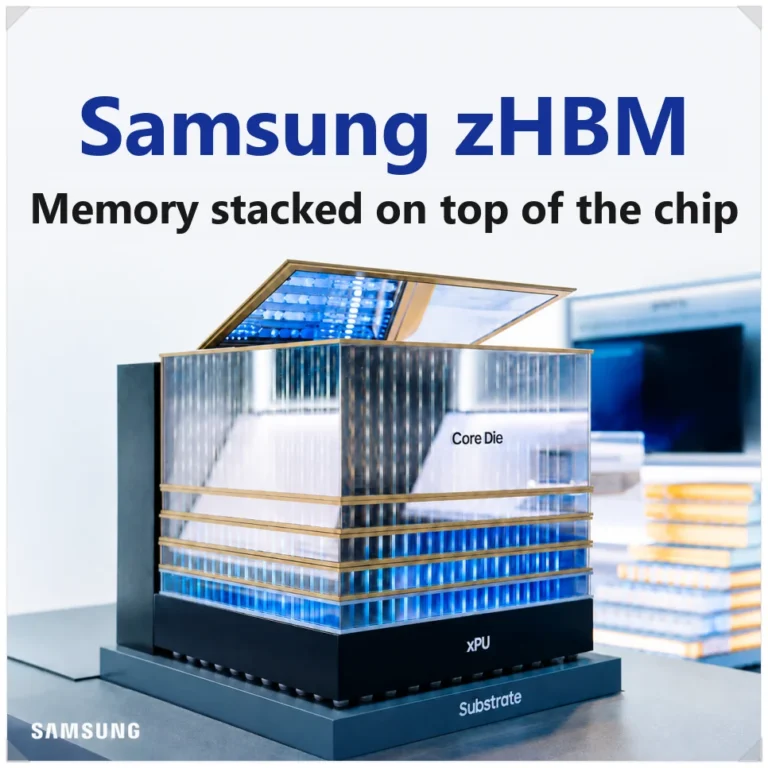
Samsung’s zHBM mockup at FMS 2026 stacks memory on the AI accelerator itself. It claims about 8x HBM5 performance, but heat, bonding yield and ecosystem costs stand in the way.
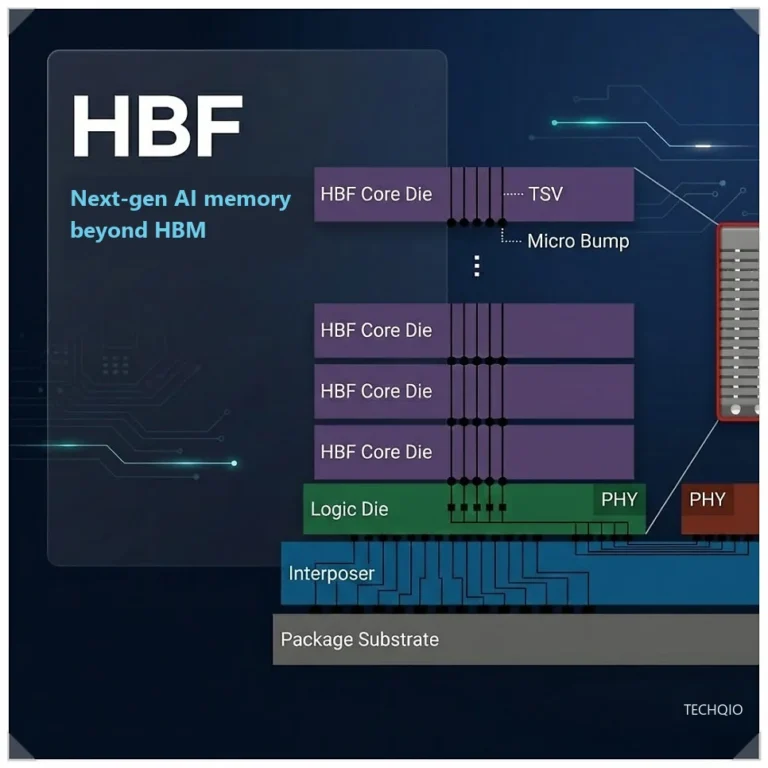
High Bandwidth Flash stacks NAND the way HBM stacks DRAM. It holds far more per stack than HBM4 at somewhat lower speed, and its first specification came out in August 2026.
GlobalFoundries will make silicon interposers for TSMC’s CoWoS packaging in New York. Interposers link GPUs and HBM in AI chips, and US-made supply starts ramping in 2028.
Anthropic’s Q3 2026 revenue reportedly reached $16.8 billion with an adjusted profit. Slowing growth and $518 billion in compute commitments explain why the AI bubble debate isn’t going away.