AI Inference Memory: How HBF, CXL and CMX Cut Costs
Inference makes AI memory capacity and cost efficiency as important as speed. HBF, CXL memory pooling and NVIDIA’s CMX each add a tier below HBM to hold KV cache and context more cheaply.

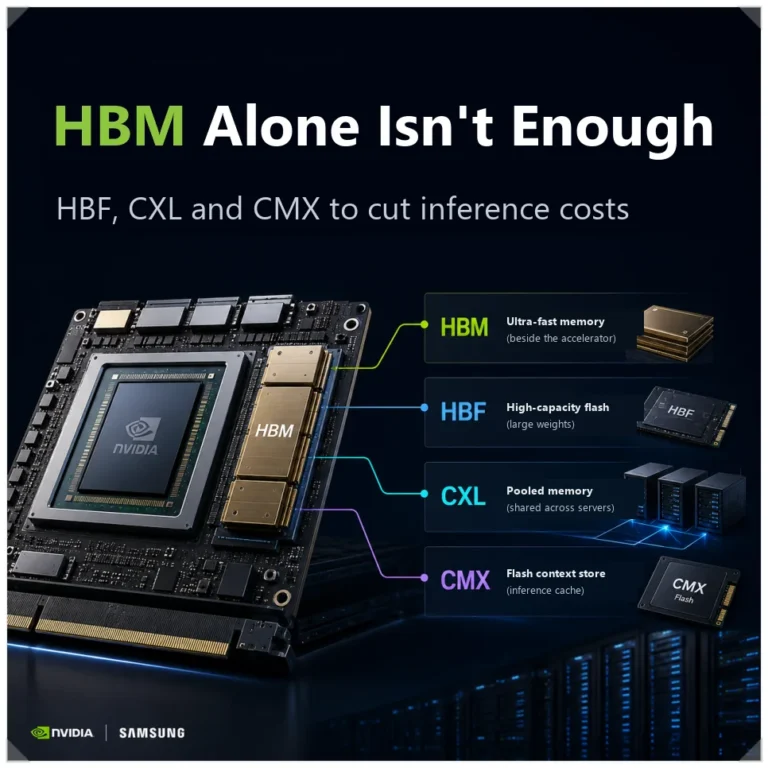
Inference makes AI memory capacity and cost efficiency as important as speed. HBF, CXL memory pooling and NVIDIA’s CMX each add a tier below HBM to hold KV cache and context more cheaply.